devwithjev
— reading now— views
Submit a build

Research & data

56 builds · page 2 of 2

John ResigJohn Resig@jeresig𝕏
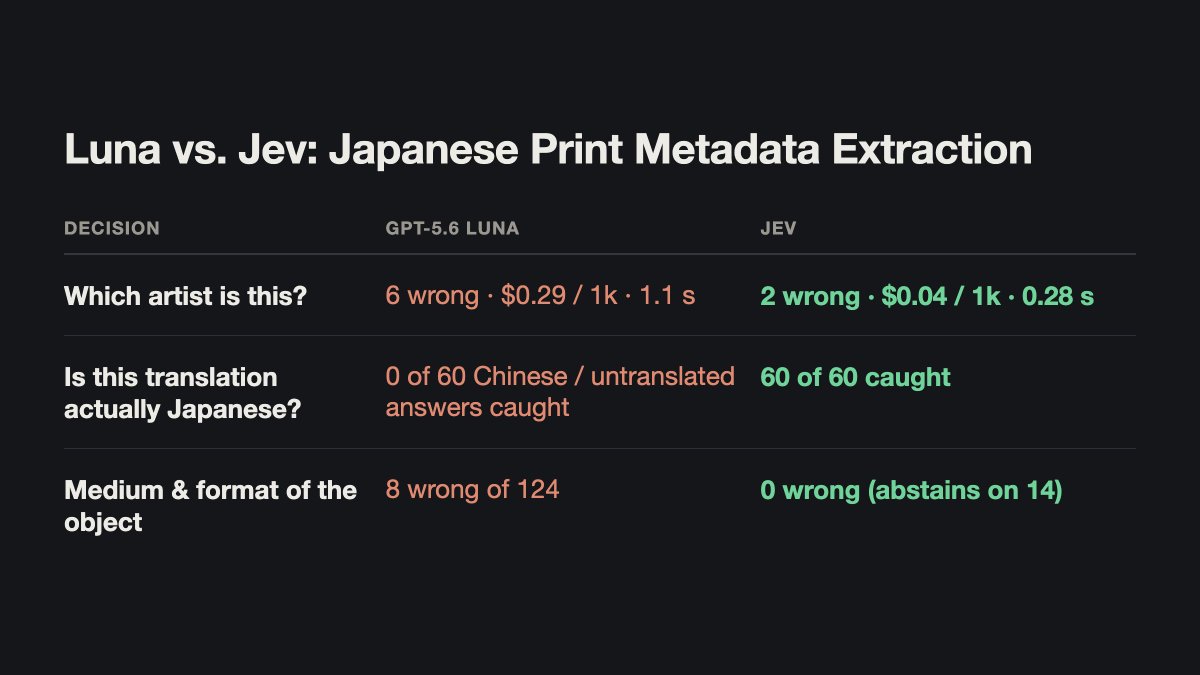
I just had to explore using Jev with my existing Japanese print metadata extraction pipeline (where I use gpt-5.6 luna). Turns out that in some cases I could replace luna completely and save a bunch of money - in others I could augment what I had for higher quality! https://t.co/iSFOGPJjf8
0160X posts·Research & dataOriginal source ↗
vehas@vehas
Charts: TypeSafe Jev evaluated on Thai standardized exams vs 110 other models.
1199GitHub·Research & dataOriginal source ↗
smasato@smasato
Jev (TypeSafe) 性能評価プロジェクト — 日本郵便 KEN_ALL をマスタに、AI SDK 経由の Jev が住所のあいまい一致にどこまで使えるかを検証.
1195GitHub·Research & dataOriginal source ↗
Menny1337@Menny1337
TypeScript experiments, evaluations, and latency benchmarks for TypeSafe's Jev model.
1192GitHub·Research & dataOriginal source ↗
zsavage8@zsavage8
Typed-decision benchmark from PadFlow (land development SaaS): schemas, anonymized labeled rows, and a runner for confidence-calibrated models like TypeSafe Jev.
1187GitHub·Research & dataOriginal source ↗
shibadogcap@shibadogcap
AI benchmark on Japan's 2026 Common Test: Jev vs luna-none vs luna-low (static dashboard).
1184GitHub·Research & dataOriginal source ↗
TokenTrim@TokenTrim
Benchmarking Jev (Typesafe.ai) against a strong LLM on the Who&When Pro agent-failure-attribution benchmark (text subset).
1178GitHub·Research & dataOriginal source ↗
anisselbd@anisselbd
Jev (TypeSafe) vs Claude Haiku 4.5 on 2 000 phishing emails: accuracy, calibration, latency, cost. Reproducible benchmark.
1174GitHub·Research & dataOriginal source ↗
anessbelbati@anessbelbati
Can a decision model beat dedicated rerankers? TypeSafe Jev vs Cohere Rerank 4 vs ZeroEntropy zerank-2 vs a chat-model baseline: 14 datasets, every raw API response, bootstrap ranges on every gap.
1116GitHub·Research & dataOriginal source ↗
RINNECODER@RINNECODER
Independent Jev 1.13.0 behavior study: report, controlled prompt experiments, raw results, and offline verification.
1113GitHub·Research & dataOriginal source ↗
AkashPriyadarshii@AkashPriyadarshii
High-throughput synthetic & pretraining dataset sifter powered by TypeSafe AI Jev (api.typesafe.ai). Stream, filter, and score Parquet & JSONL datasets at 1,500+ rows/sec using System One typed decisions (Choice, Score, Noul).
1110GitHub·Research & dataOriginal source ↗
zhuyansen@zhuyansen
Does a TypeSafe Jev rerank beat embedding search? Graded relevance eval (9,831 pairs, 164 zh/en queries) over the Agent Skills Hub catalog, with the judge-circularity bias measured.
1109GitHub·Research & dataOriginal source ↗
mahlernim@mahlernim
Reproducible early-access evaluation of Jev on Korean understanding and medical text, with runtime and cost evidence.
1106GitHub·Research & dataOriginal source ↗
zhihz@zhihz
Local bilingual probability decisions from context, questions, and candidate answers. Independent research preview inspired by TypeSafe Jev.
1096GitHub·Research & dataOriginal source ↗
rorshopping@rorshopping
Unofficial study: Jev-style parallel typed decisions on stock 1.5B-8B models on an Apple Silicon laptop. Benchmarks, research notes, and a Hugging Face Space demo.
1093GitHub·Research & dataOriginal source ↗
r-ms@r-ms
Mini-Jev: what a Jev-style typed-decision interface looks like on a frozen Qwen3-4B — read the option letter's logits instead of generating JSON. Preregistered experiment, results, teaching bench.
1092GitHub·Research & dataOriginal source ↗